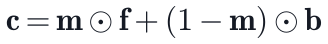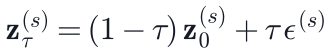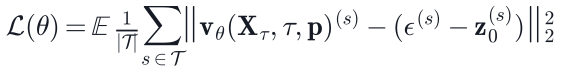Applied Research

Video LayerGen

Generative Video Layer Decomposition and Harmonization — one video diffusion transformer that pulls a shot apart into editable layers, and composites them back with physically consistent shadows, reflections and contact.
Adobe Applied Research
1shared model · both directions
206,852layered-video clips
4packed layer streams
14Bvideo diffusion transformer
TL;DR

Video editing is a layered process. LayerGen casts both decomposition (composite + mask → foreground + background) and harmonization (foreground + background → composite) as complementary noising patterns over one packed token sequence, so a single video diffusion transformer performs both — matching or beating task-specialized methods on object removal while recomposing layers with coherent shadows, reflections and contact.

Abstract

One model for pulling video apart — and putting it back together

Professional video editing is fundamentally a layered process: a shot is pulled apart into an editable foreground and a clean background, and layers are composited back into a photorealistic result. Generative video models, however, address these operations in isolation and mostly on images — transparency-aware video models emit only a single foreground, while decomposition (matting, omnimatte, object removal) and compositing are studied as separate problems, all constrained by the scarcity of video with ground-truth layers.

We present LayerGen, a single video diffusion transformer that unifies video layer decomposition and harmonization. LayerGen packs the four layer streams — composite, foreground, background, and mask — into one in-context token sequence and casts each task as a noising pattern: conditioning streams are supplied clean while target streams are denoised, with learnable stream-type and task-type embeddings selecting the layer and the direction. To address data scarcity we build a data engine that animates licensed 4K layered stock and renders counterfactual object-removal triplets from BEDLAM2 and Kubric. Across video object-removal benchmarks LayerGen matches or surpasses task-specialized state-of-the-art — improving physically consistent background reconstruction and attaining the best in-the-wild removal coherence — while the same weights recompose foreground and background into composites with temporally coherent lighting, shadows, reflections, and contact.

Contributions
  • ◧A unified layered-video model. Decomposition and harmonization as complementary noising patterns over one packed stream sequence.
  • ▤A data engine for layered video. Ken-Burns animation of 4K stock + physically-rendered counterfactual triplets = 206,852 clips (256K task views).
  • ✦Grounded supervision & augmentations. Edit-style captions, size-adaptive mask perturbation, foreground warp & occlusion.
  • ★State-of-the-art results. Best background reconstruction & in-the-wild coherence; same weights harmonize.

Method

A single transformer, two noising patterns

Each layer stream is VAE-encoded, patchified, and tagged with a learnable stream-type embedding; the streams are packed into one token sequence with a task-type embedding and processed by a full-attention DiT. A task-specific noising pattern marks clean condition streams (τ=0) and noised target streams; flow-matching supervises only the targets.

LayerGen architecture
The shared trunk (VAE, DiT, umT5). Stream-type + task-type embeddings are added to every token; dotted = noised targets, solid = clean conditions. Click to enlarge.
Alpha-over compositing
composite equation
Rectified-flow noising (targets)
flow equation
Flow-matching loss (targets only)
loss equation

Decomposition conditions on {composite, mask} and denoises {foreground, background}. Harmonization conditions on {background, occluded foreground observation f̃} and denoises {composite, complete foreground}.

Data engine

Where ground-truth layered video comes from

Three complementary sources yield true (foreground, background, composite) triplets: layered 4K stock animated with a virtual camera, and physically-rendered counterfactual with/without-object renders from BEDLAM2 and Kubric.

LayerGen data engine

Explore the training triplets

Pick a source and a task direction — videos play in sync.


Results · Decomposition

Object removal & layer extraction

Given a composite and a target mask, LayerGen recovers a clean background (and the isolated foreground). Compare against baselines — videos play in sync. Add baselines from the menu; scroll horizontally for more.

Results · Harmonization

Compositing with physical consistency

Given a foreground and a background, LayerGen synthesizes a composite with coherent shadows, reflections, relighting and contact — the same weights as decomposition.


Quantitative results

Benchmarks

Numbers from the paper. Best per column is bold; LayerGen rows are highlighted.

Cite

BibTeX

@article{layergen2026,
  title   = {Video LayerGen: Generative Video Layer Decomposition and Harmonization},
  author  = {Anonymous},
  journal = {arXiv preprint},
  year    = {2026}
}

Videos stream from public HuggingFace datasets (cs-mshah/layergen-evals · -baselines).